- Transformer layers with multi-head attention
- Shared hidden-state representations
- Multiple specialized predictive pathways for direction, volatility, price change, and spread
- Batch normalization to stabilize training
- Focal loss implementation to address inherent class imbalance
Mathematical Foundations: Functions and Formulas
Positional Encoding
Sinusoidal positional encoding represents each position in a sequence: Wherepos is the position within the sequence and i is the dimension index.
Focal Loss for Direction Prediction
Focal loss adjusts the contribution of examples during direction-prediction training: Wherep_t is the model’s estimated probability for the correct class and γ is the focusing parameter. Increasing γ reduces the contribution of examples for which the model already assigns a high probability to the correct class.
Confidence Calibration
Hanabi-1 computes a confidence score from the distance between the predicted probability and the decision threshold: Wherep is the predicted probability and threshold is the decision boundary. Users can filter predictions by this score.
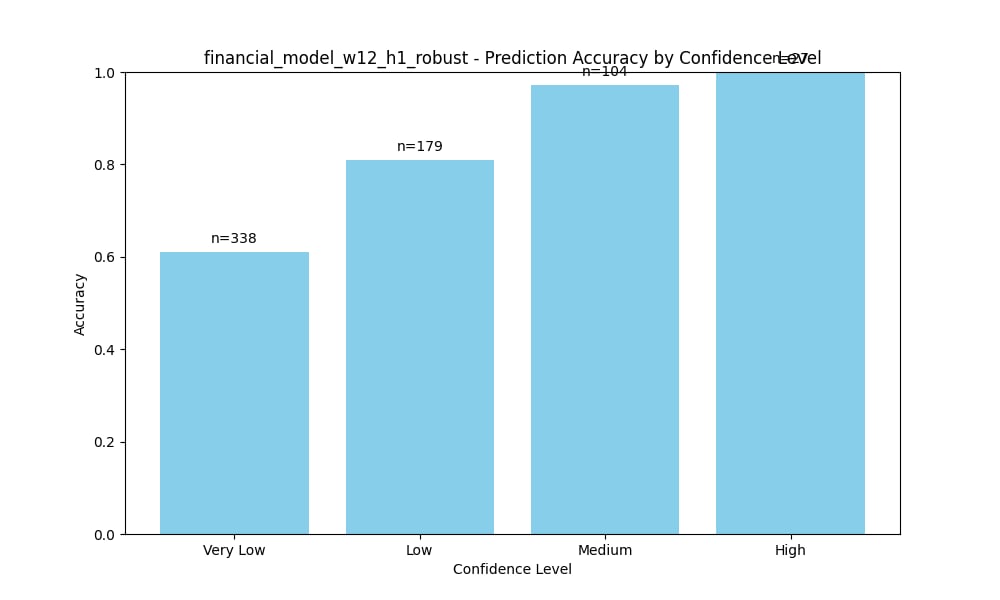 Confidence vs Accuracy
The plotted evaluation groups predictions by confidence. The reported accuracy is nearly 100% in the “High” group and close to chance in the “Very Low” group.
Training Dynamics and Balanced Validation
The validation score penalizes imbalanced predictions, including collapse to a single predicted class: Where is the precision-recall balance metric: And applies severe penalties for extreme prediction distributions: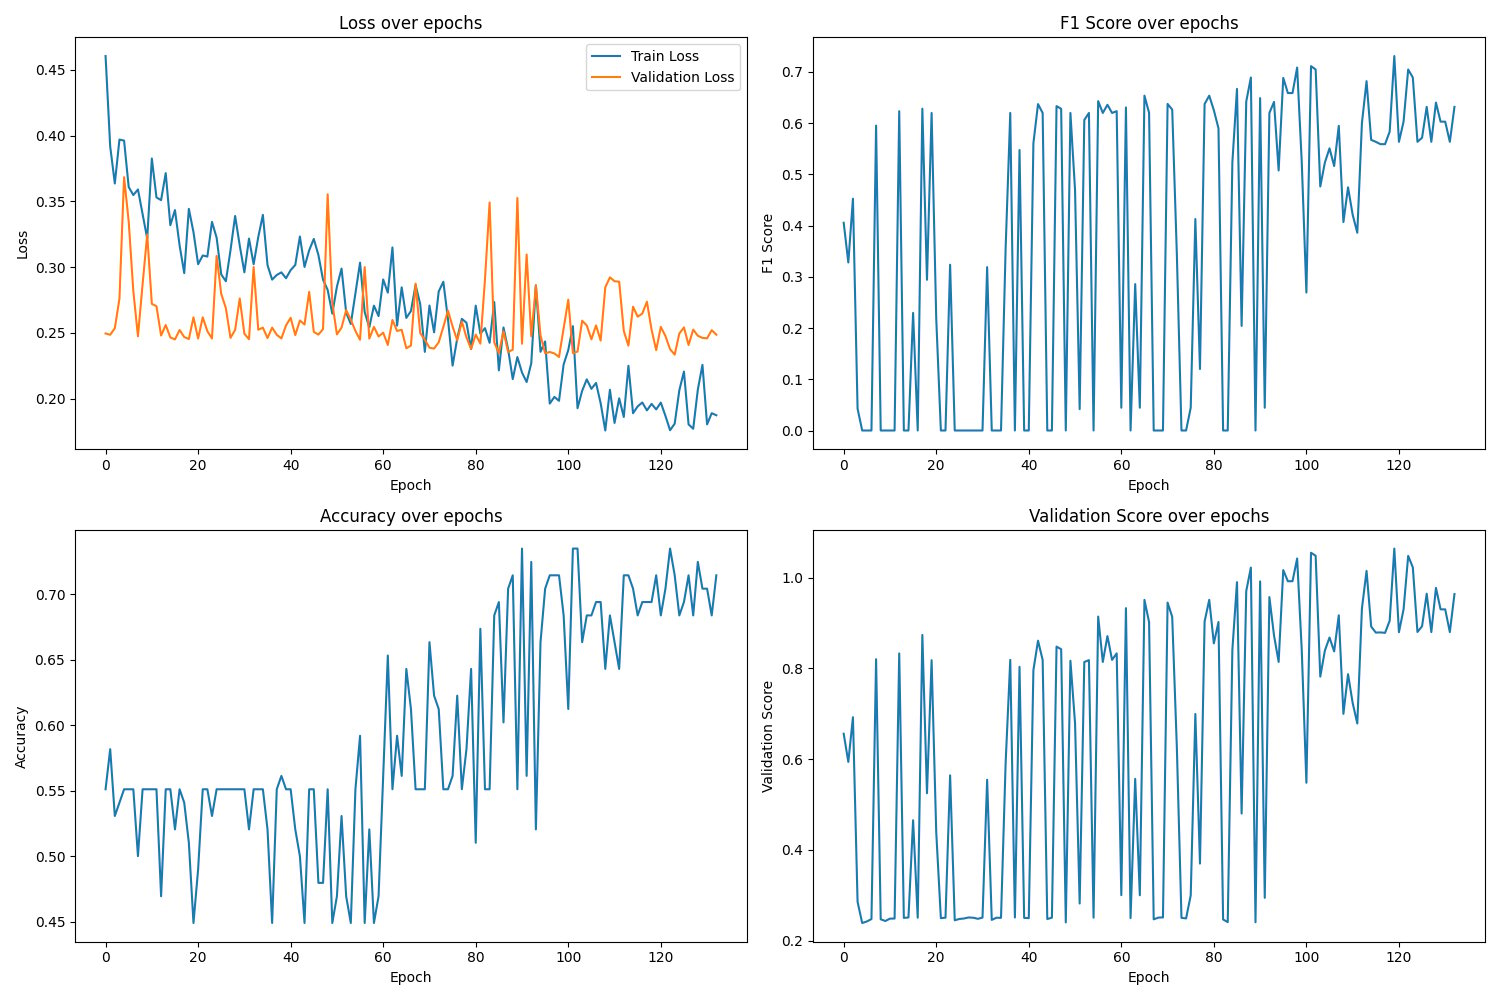 Training dynamics
The plot records training and validation changes over the displayed run.
Model Architecture Details
The architecture combines temporal aggregation with task-specific prediction pathways:- Feature differentiation through multiple temporal aggregations:
- Last hidden state capture (most recent information)
- Average pooling across the sequence (baseline signal)
- Attention-weighted aggregation (focused signal)
- Direction pathway with BatchNorm for stable training:
- Fully connected layers with BatchNorm1d
- LeakyReLU activation to keep a nonzero gradient for negative inputs
- Xavier initialization with small random bias terms
- Specialized regression pathways:
- Separate networks for volatility, price change, and spread prediction
- Reduced complexity compared to the direction pathway
- Independent optimization focuses training capacity where needed
Prediction Temporal Distribution
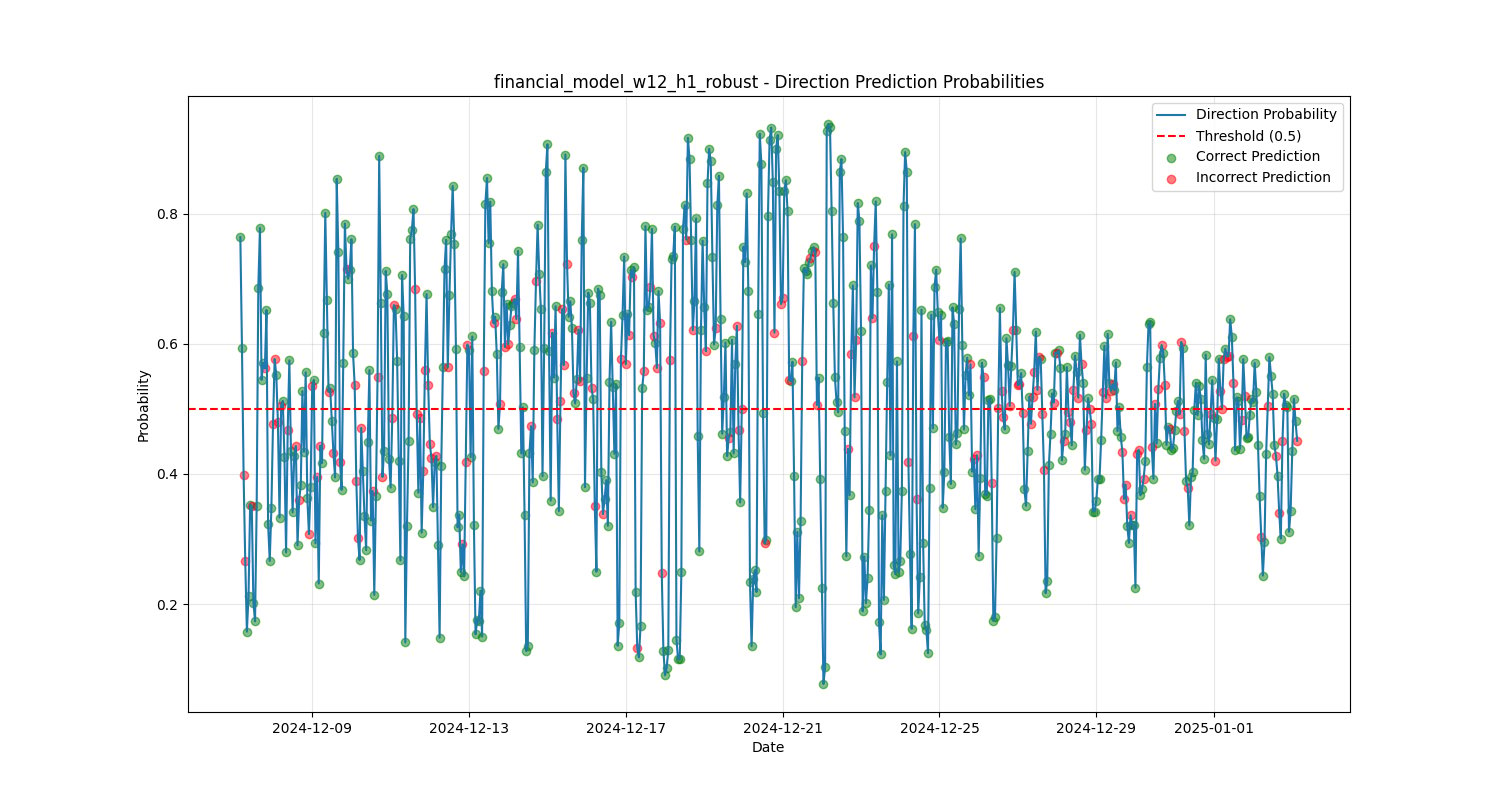 Direction Probabilities
The plot shows directional predictions over time. Green dots mark correct predictions; red dots mark incorrect predictions.
Performance and Future Directions
Reported evaluation metrics:- Direction accuracy: 73.9%
- F1 score: 0.67
- Balanced predictions: 54.2% positive / 45.8% negative
- 4-hour window model (w4_h1)
- 12-hour window model (w12_h1)
- Extending prediction horizons to 4, 12 and 24 hours
- Implementing adaptive thresholds based on market volatility
- Adding meta-learning approaches for hyperparameter optimization
- Integrating on-chain signals for cross-domain pattern recognition